Updated October 22, 2026. Part of the survey research guide. For the full PR workflow, see the PR survey guide.
Survey sample size (the number of respondents who complete a survey) is the variable communications teams ask about most often and understand least well. The right sample size depends on what claims the research needs to support, how much sub-group analysis is required, what margin of error is acceptable, and how the findings will be distributed. A 200-respondent survey can produce defensible findings for some purposes and indefensible findings for others. A 30,000-respondent survey can be appropriate for some research designs and a waste of investment for others.
This guide covers what each respondent scale enables, the margin-of-error math that anchors the decision, when to over-invest, and when a smaller sample is acceptable.
What is the margin of error at each sample size?
For a probability sample asking a single yes/no question, the margin of error at 95% confidence is approximately ±1/√N expressed as a proportion. The table shows common sample sizes.
| Respondents (N) | Margin of error (points) |
|---|
| 100 | ±9.8 |
| 200 | ±6.9 |
| 400 | ±4.9 |
| 600 | ±4.0 |
| 1,000 | ±3.1 |
| 1,500 | ±2.5 |
| 2,500 | ±2.0 |
| 5,000 | ±1.4 |
| 10,000 | ±1.0 |
| 30,000 | ±0.6 |
At N = 100, a finding of 50% support could reflect actual support anywhere from 40.2% to 59.8%. The pattern is diminishing returns. The improvement from 1,000 to 2,000 respondents is roughly 1 percentage point, and the improvement from 10,000 to 30,000 is roughly 0.4 points. Above about 2,500 to 5,000 respondents, extra sample barely improves the overall margin of error, though it remains valuable for sub-group analysis.
The formula applies to probability samples. Most commercial surveys use non-probability online panels, so treat these figures as a guide and disclose the panel provider and weighting. The PR survey guide covers sample design, weighting and mode.
What does each sample size enable?
Six practical scales, each with its typical use.
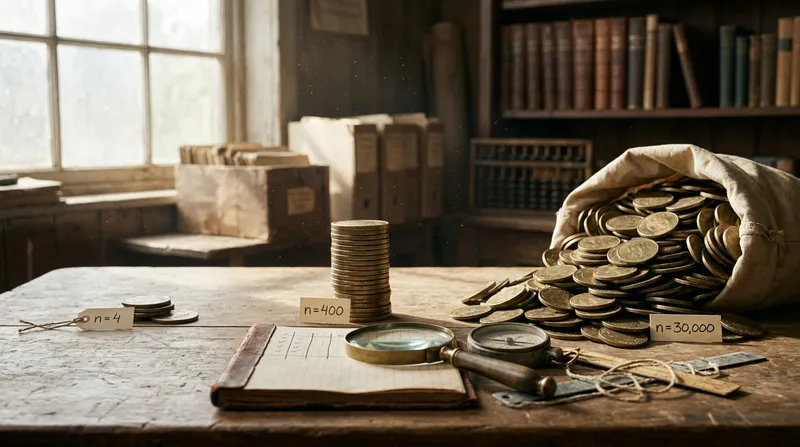
- N = 100 to 200: discovery and concept testing. Suited to early exploration, message testing among small specialist audiences, internal feedback, and pre-testing larger studies. Margins of error are too wide for projectable claims, so the output is directional. Journalists will flag a sample this small, so it is not a press-tactical scale.
- N = 400 to 600: single-question press research. Suited to surveys that produce one headline finding for press. The roughly ±5-point margin works for claims that do not depend on small margins. "62% of Americans report doing X" is defensible at N = 400, while "51% vs 49% on a contested question" is not.
- N = 1,000: the conventional national survey. The default for most political polling, major brand surveys, and consumer research with national claims. The ±3-point margin supports the point-estimate claims most communications use cases need. Sub-groups work for major demographic categories but break down for narrow intersections such as age by race by education.
- N = 1,500 to 2,500: sub-group analysis at scale. Suited to research that must support defensible comparisons across demographics, regions, or behavioral segments. The Edelman Trust Barometer, with 30,000 or more respondents across about 28 countries, averages roughly 1,100 per country to support country-level comparisons.
- N = 5,000 to 10,000: multi-segment franchise research. Suited to designs that produce findings across many sub-groups at once. The J.D. Power Vehicle Dependability Study and the Pew American Trends Panel operate at this scale because each brand, demographic, or topic needs its own defensible sample.
- N = 30,000 or more: global or hyper-granular research. Suited to global studies and national designs that need narrow sub-group projectability. The MetLife Employee Benefit Trends Study and the Gallup State of the Global Workplace report operate at this scale.
Why does sub-group size drive the sample you need?
The most common mistake communications teams make is under-investing in sample size for the sub-group analysis the research is supposed to support.
A 1,000-respondent survey produces a ±3-point margin on overall findings. But the sub-group "women in California aged 18 to 34" within that sample may include only 25 respondents, which produces a ±20-point margin for that sub-group. Findings that look rigorous overall can be statistically meaningless at the sub-group level.
Before commissioning research, list every sub-group claim the study needs to support and verify the expected sample within each one. Most methodologists treat a minimum sub-group N of 100 (±9.8 points) as the floor, with N = 200 (±6.9 points) as a more defensible floor for important findings. Studies with many sub-group claims need larger overall samples than studies with headline-level findings only.
How big should the sample be for specific use cases?
- Press release research. N = 400 to 1,000 is adequate when findings are headline-level. "72% of Americans report Y" is defensible at N = 1,000. "78% of women aged 25 to 34 in the Pacific Northwest report Y" needs that sub-group's own defensible sample.
- Brand tracking. N = 300 to 600 per measurement period, with the series across waves providing the analytical depth.
- Annual franchise research. N = 2,000 to 30,000, because scale anchors long-term credibility and supports granular sub-group findings every year.
- Political polling. N = 1,000 to 1,500 nationally and 500 to 1,000 per state. Crosstab needs drive most of the sample-size decisions.
- Employee research. Internal employee surveys usually census the whole workforce, so the question is the response-rate threshold. A response rate of 60% or more is typically considered defensible for sub-group analysis.
- B2B research. N = 200 to 2,000, because B2B populations are smaller and per-respondent costs are higher. The PR survey guide compares consumer and B2B designs in full.
When should you over-invest in sample size?
Three conditions justify a sample larger than the headline analysis requires.
- The research will produce multi-year citation value. The Edelman Trust Barometer's scale is justifiable because it compounds across two decades of citation. A one-time press release does not justify the same scale.
- Sub-group analysis is central to the design. The J.D. Power studies need a defensible sample inside each automotive brand.
- The research will face a scrutinized media environment. Findings likely to be examined by hostile journalists, competitor analysts, or regulators should be over-engineered for defensibility.
When is a smaller sample acceptable?
Three conditions justify a smaller sample than maximum rigor would prefer.
- The research is for internal management decisions. A 200-respondent customer survey that informs a product decision does not need the rigor of a press-released study.
- The findings are directional. Early signals such as "customers lean toward A over B" can use smaller samples if the findings are described honestly as directional.
- The research is part of a continuous-tracking program. Individual waves can be smaller because the longitudinal series provides depth, as long as no single wave is treated as definitive.
What are the five operating lessons for communications teams?
- Start from the sub-group analysis, not the overall sample. The overall sample size flows from the sub-group requirements.
- Match sample size to the use case. Discovery research (N = 100 to 200) differs from press research (N = 400 to 1,000), which differs from franchise research (N = 5,000 or more).
- Treat 1,000 as a default for headline-level claims only. It produces the ±3-point margin that supports point-estimate press claims. Over-invest when sub-groups are central.
- Disclose sample size. After the 2016 polling misses covered in Polling Errors That Change Headlines, journalists routinely check sample sizes. Surveys sized to their claims get favorable coverage, and mismatched ones get questioned.
- Watch the diminishing-returns curve. Above N = 2,500, budget usually does more good redirected to better questionnaire design, larger sub-group cells, or extra waves.