Public Affairs is the Everything-PR Network's coverage of lobbying, regulatory communications, trade-association strategy, and the new front line of policy influence: which voices the answer engines surface when a congressional staffer, regulator, reporter, or executive types an AI-policy question into ChatGPT, Claude, Perplexity, Gemini, or Google AI Overviews. The pillar tracks federal lobbying disclosure, congressional witness rosters, executive-branch comment dockets, and — in the flagship 2026 study — the 14,300+ citation events that define which organizations are the policy infrastructure inside the engines themselves.
The 2026 Flagship — The AI Policy Visibility Gap
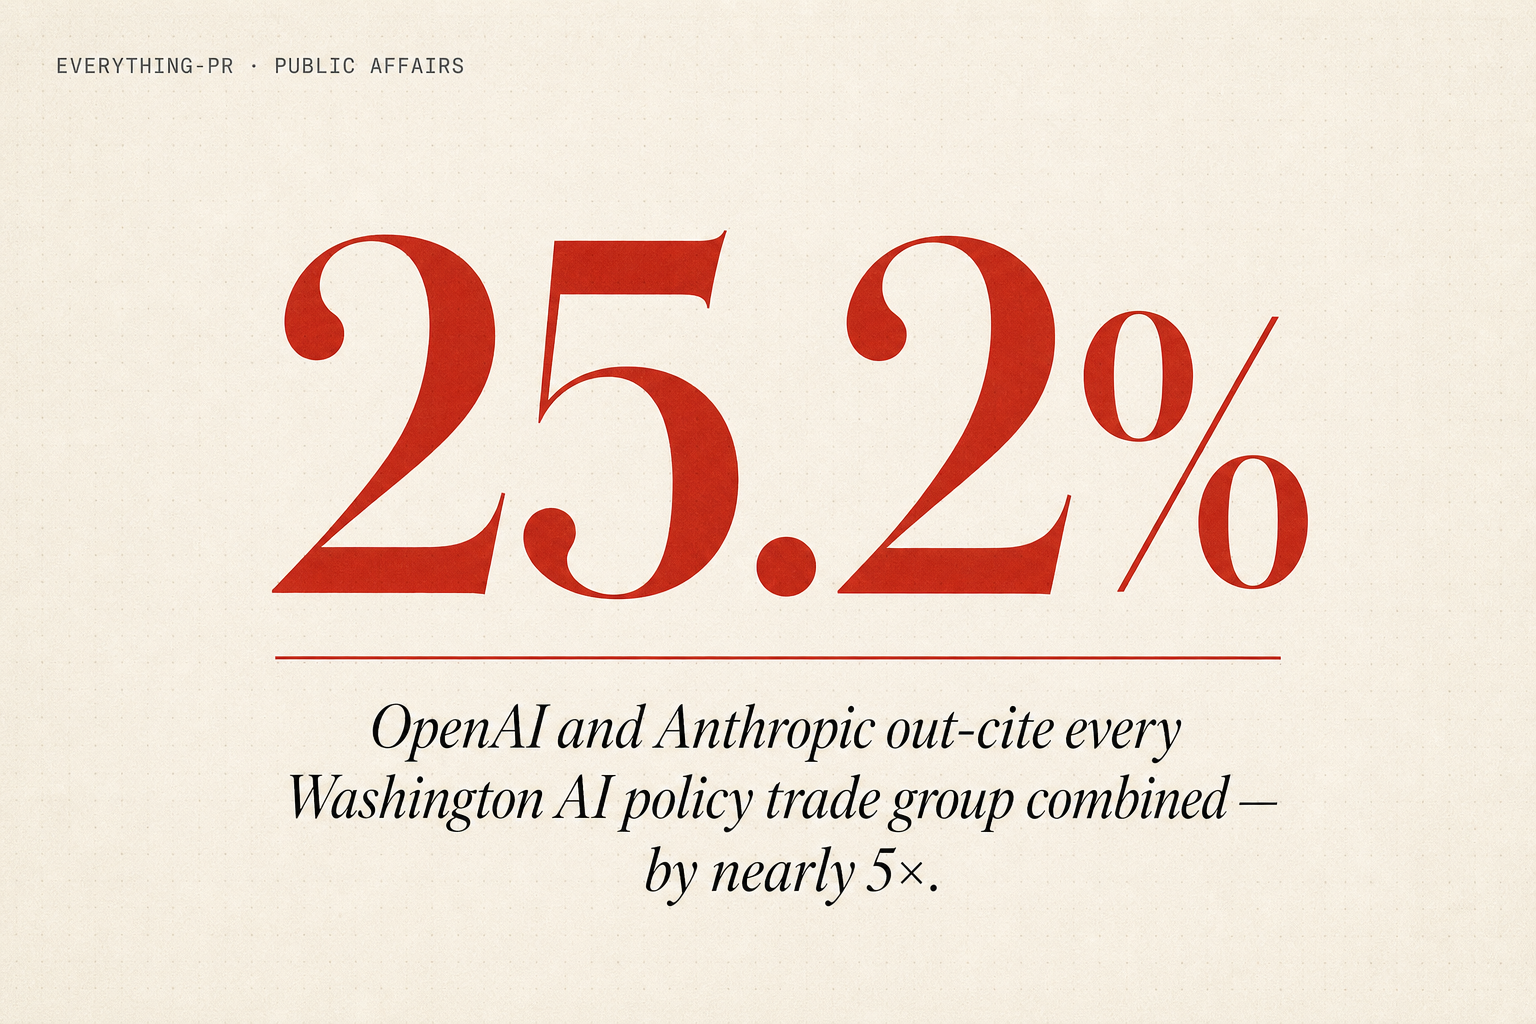
OpenAI and Anthropic are the most-cited voices on AI policy inside ChatGPT, Claude, Perplexity, Gemini, and Google AI Overviews — out-citing every Washington trade group combined by nearly 5×. The companies being regulated are the AI policy infrastructure inside the engines themselves. Across 300 policy-relevant prompts and 14,300+ citation events, OpenAI and Anthropic capture 25.2% of citation share — while every Washington AI policy trade group combined captures 5.3%.
300 prompts tested. 5 AI engines. 30 voices measured. 14,300+ citation events. Field window: Q1 2026. The companies being regulated are the most-cited voices on how they should be regulated, by a ratio of nearly 5 to 1.
Key Findings
Finding 01 — OpenAI and Anthropic are the citation engine (25.2%)
OpenAI alone captures 13.8% of citation share across the five major AI engines. Anthropic captures 11.4%. Combined: 25.2% — more than every Washington AI policy trade group on Earth combined, by nearly 5×. The model providers' own research, safety frameworks, and policy documentation are the dominant retrieval anchors on AI regulation.
Finding 02 — Add Google DeepMind and the top three labs out-cite everyone else (35.7%)
OpenAI + Anthropic + Google DeepMind = 35.7% of all AI policy citation share. The eight Washington trade groups in the study, combined, capture 5.3%. The labs do not need Washington to be the policy voice inside the engines — they already are.
Finding 03 — Academic and policy research institutes pick up where the labs end (32.1%)
Stanford HAI (8.7%), Brookings (7.2%), RAND (5.2%), CSET–Georgetown (4.6%), Center for AI Safety (5.9%), and AI Now (3.0%) account for 32.1% combined. Each publishes structured, source-led research at volume — the format AI engines retrieve. Lobbying memos and press releases do not surface.
The Leaderboard — Citation Share Across All Five AI Engines
The thirty voices were ranked on Citation Share (percentage of attributed citations across the 14,300+ retrievable answer outputs) against DC Rank (a composite of federal lobbying spend, AI-relevant congressional witness appearances 2024–2026, and policy-press mentions in Politico, Punchbowl, Axios, Semafor, and The Information). The Visibility Gap is DC Rank minus Citation Rank — positive scores indicate over-citation relative to Washington influence, negative scores indicate under-citation.
Top 10 by Citation Share
1. OpenAI — 13.8% (DC #6, +5) 2. Anthropic — 11.4% (DC #9, +7) 3. Stanford HAI — 8.7% (DC #18, +15) 4. Brookings Institution — 7.2% (DC #15, +11) 5. Google DeepMind — 6.5% (DC #7, +2) 6. Center for AI Safety — 5.9% (DC #24, +18) 7. RAND Corporation — 5.2% (DC #17, +10) 8. CSET — Georgetown — 4.6% (DC #19, +11) 9. Microsoft (AI Policy) — 3.8% (DC #8, −1) 10. Future of Life Institute — 3.4% (DC #25, +15)
Most Under-Cited Relative to Washington Influence
Heavy DC presence, low AI engine retrieval. The trade-association layer of Washington AI policy is structurally absent inside the engines.
- BSA — The Software Alliance — DC #3, gap −23
- ITI — Information Technology Industry Council — DC #2, gap −22
- U.S. Chamber of Commerce — DC #1, gap −19
- NetChoice — DC #4, gap −19
- SIIA — DC #11, gap −16
- Frontier Model Forum — DC #5, gap −12
Most Over-Cited Relative to Washington Influence
Low DC presence, high AI engine retrieval. Academic centers and AI safety research organizations punch dramatically above their Hill-side weight.
- Center for AI Safety — DC #24, gap +18
- Stanford HAI — DC #18, gap +15
- Future of Life Institute — DC #25, gap +15
- Brookings Institution — DC #15, gap +11
- CSET — Georgetown — DC #19, gap +11
- RAND Corporation — DC #17, gap +10
By Engine — The Five AI Engines Do Not Cite the Same Voices
Where a policy organization surfaces depends on where each engine retrieves.
ChatGPT — OpenAI · Highest concentration
OpenAI 17.2% · Anthropic 10.8% · Brookings 8.1% · Stanford HAI 7.9% · Center for AI Safety 6.4%.
Claude — Anthropic · Research-weighted
Anthropic 15.6% · Stanford HAI 10.2% · OpenAI 9.4% · Center for AI Safety 7.8% · RAND 6.1%.
Perplexity — Web-grounded · Recency-weighted
OpenAI 14.1% · Anthropic 12.3% · Stanford HAI 9.6% · Brookings 7.8% · Google DeepMind 7.2%.
Gemini — Google · DeepMind-favored
Google DeepMind 14.8% · OpenAI 11.6% · Stanford HAI 8.4% · Anthropic 7.9% · Brookings 6.7%.
Google AI Overviews — Search-blend · News-anchored
OpenAI 15.4% · Anthropic 10.9% · Stanford HAI 9.1% · Brookings 8.6% · RAND 5.8%.
By Prompt Category — The Voices That Surface Depend on the Question
Citation share is not uniform across topics. Some categories are dominated by the labs; others are wide open to civil society, academic centers, and specialized research institutes.
AI Regulation & Federal Frameworks (42 prompts)
Representative query: "What are the leading proposals for U.S. federal AI regulation in 2026?" Top voices: Stanford HAI, Brookings, OpenAI, CSET, Anthropic.
AI Safety & Existential Risk (38 prompts)
Representative query: "What organizations are leading research on catastrophic AI risk?" Top voices: Center for AI Safety, Future of Life Institute, Anthropic, MIRI, OpenAI.
Algorithmic Discrimination & Bias (34 prompts)
Representative query: "How should employers audit AI hiring tools for bias?" Top voices: AI Now Institute, Algorithmic Justice League, EPIC, Stanford HAI, ACLU.
Copyright & Training Data (31 prompts)
Representative query: "What is the legal status of AI model training on copyrighted content?" Top voices: OpenAI, EFF, Anthropic, Stanford HAI, CDT.
National Security & AI (29 prompts)
Representative query: "What are the national security implications of frontier AI models?" Top voices: RAND, CSET — Georgetown, Anthropic, OpenAI, Center for AI Safety.
Compute Governance & Export Controls (26 prompts)
Representative query: "How is access to advanced AI compute being regulated globally?" Top voices: CSET — Georgetown, RAND, Brookings, Anthropic, Stanford HAI.
Open Source vs Closed Models (24 prompts)
Representative query: "What is the policy debate around open-weight AI models?" Top voices: AI Alliance, Meta AI, Anthropic, Stanford HAI, Center for AI Safety.
Workforce, Labor & Displacement (22 prompts)
Representative query: "What is the projected impact of AI on U.S. employment?" Top voices: Brookings, RAND, Stanford HAI, OpenAI, AI Now Institute.
Election Integrity & Synthetic Media (28 prompts)
Representative query: "How are AI-generated election disinformation risks being addressed?" Top voices: Stanford HAI, Brookings, Partnership on AI, EPIC, CDT.
Child Safety & Online Harms (26 prompts)
Representative query: "What AI policy frameworks address child safety online?" Top voices: EPIC, Stanford HAI, CDT, OpenAI, Anthropic.
Methodology — How Citation Share Was Measured
The Test
300 prompts. Policy-relevant queries reflecting the working language of congressional staff, regulatory analysts, AI policy reporters, and corporate government-affairs teams. 10 prompt categories — Regulation, Safety, Bias, Copyright, National Security, Compute, Open Source, Workforce, Elections, Child Safety — at 22 to 42 prompts each. 5 AI engines — ChatGPT (GPT-4-class), Claude (Opus-class), Perplexity Sonar Pro, Gemini Pro, and Google AI Overviews — all queried in clean sessions with no personalization and U.S. locale. 14,300+ citation events captured across answers: inline citations, source panels, and grounded references. Field window: Q1 2026. Single window, single methodology pass.
The Math
Citation Share % is total attributed citations to an entity divided by total attributed citations across the entire study set. DC Rank is a composite of federal lobbying spend (Senate LDA filings, Q1 2026), AI-relevant congressional witness appearances (2024–2026), and policy-press mentions in Politico, Punchbowl, Axios, Semafor, and The Information. Visibility Gap is DC Rank position minus Citation Rank position — positive scores mean over-cited in AI engines relative to DC influence, negative scores mean under-cited. Engine strength is tertile-binned citation share per engine.
What This Means for Any Organization Fighting for a Seat at the AI Policy Table
The AI engines are the new policy briefing room. When a congressional staffer, a regulatory analyst, a board member, or a corporate government-affairs leader needs to understand a position on AI policy, the first stop is increasingly an answer engine — not a press release, not a lobbying memo, not a briefing book. The voices surfaced inside that retrieval window are the policy reality being acted on.
Hill-side influence does not transfer. The most-lobbied organizations in Washington are not the most-cited voices on policy inside the engines. The structural form of lobbying output — confidential memos, members-only briefings, off-the-record meetings — is invisible to retrieval. The form that surfaces is published, sourced, structured research.
Citable, sourced, structured. Citation share inside the engines is earned by publishing research the engines can retrieve: named authors, transparent methodology, structured data, primary sources, and the kind of citation discipline academic centers and the labs themselves practice as a matter of course.
Citation share is built, not bought. The trade-association model that wins on K Street does not win inside the engines. Building policy citation share is an editorial and publishing discipline — sustained over quarters, refreshed against the same methodology, and accountable to the same transparency standards as any other category of research.