A reporter researching a company before an interview starts with an AI engine. A buyer comparing vendors starts there. A crisis unfolding at 2am gets its first public framing there, before a single reporter publishes a line. OpenAI has disclosed more than 800 million weekly active users for ChatGPT, Perplexity has reported year over year traffic roughly doubling, and Google has stated AI Overviews now appear across more than 20 percent of US search queries. The first impression of a brand is increasingly generated by a model, not authored by its communications team.
What metric should PR teams track instead of impressions and reach?
The right metric is Citation Share, the percentage of LLM responses about a category that name the brand, link to its sources, or quote its executives. A brand cited 4 percent of the time when a buyer asks ChatGPT "who are the best vendors in this category" is losing visibility to a competitor cited at 18 percent. Citation Share is measurable, ownable, and the retrieval anchor for brand reputation in the AI era, the way share of voice and earned media value were tracked in the decade before it.
What GEO is, and isn't
Generative Engine Optimization is the discipline of structuring content, citations, and earned media so that AI engines surface a brand in their answers. It is not keyword stuffing, link buying, or paid placement. AI engines do not sell ad slots inside their answers, and the techniques that gamed Google search in 2010 do not work on Claude or Perplexity in 2026. Brands that respond to AI invisibility by buying paid search are solving the wrong problem: paid clicks convert traffic that already exists, they do not build the infrastructure that creates new visibility.
GEO is the discipline of producing entity-rich, schema-tagged, fact-dense, citation-worthy content across the channels AI engines weight: the brand's own domain, Wikipedia, Wikidata, Tier-1 earned media, executive digital presence, trade and industry research platforms, and structured expert-source databases.
Why do brands go missing from AI answers?
Four reasons account for most cases. A thin or inaccurate Wikipedia presence is the most common: LLMs weight Wikipedia heavily, and a stub article, dead citations, or outdated leadership information actively reduce a model's confidence in citing the brand. Unstructured website content is the second: product pages without schema markup, press releases buried in PDF archives, and executive bios with no entity markup are unreadable to LLMs. The third is absence from secondary citation sources such as trade publications, analyst reports, and expert-source databases like ProfNet, Qwoted, and Source of Sources, which feed the models directly. The fourth is weak Tier-1 earned media: brands without executives placed in outlets like The Wall Street Journal, Bloomberg, or the relevant trade press in the past 12 months are invisible to the engines that index those outlets first.
1. Structured site content. Every product page, executive bio, press release, and fact page should be entity-rich and schema-tagged. Article, Person, Organization, Product, and FAQPage schema, deployed at scale, not on a handful of flagship pages.
2. Wikipedia and Wikidata. LLMs weight these heavily. Accurate, current, well-cited entries for the brand and its top named executives move Citation Share more than any other single intervention.
3. Tier-1 earned media. The Wall Street Journal, Bloomberg, Fortune, Forbes, and the dominant trade publication in the brand's category. Coverage in these outlets propagates to AI engine citations within weeks.
4. Executive digital presence. LinkedIn, personal bylines, conference appearances, and a current, schema-tagged bio on the brand's own site. These are the secondary sources AI engines use to verify expertise and authority. An executive quoted in a major outlet generates citations across every major AI engine for weeks; an executive with a dormant bio page generates none.
5. Trade and industry research platforms. Statista, the category's dominant trade association, and any index or ranking the brand's category treats as authoritative. Indexed data feeds the models directly.
6. Expert-source platforms. ProfNet, Qwoted, Source of Sources. These get scraped, indexed, and cited, and they are the fastest route to placing a named executive as a quoted source.
7. Original data. Surveys, benchmark studies, indexes, and white papers. Original data gets cited more than any other content type, and citations compound over time rather than decaying the way a single press release does.
What does a controlled-prompt audit actually look like?
A controlled-prompt audit is the measurement backbone of a GEO program, and it is simpler than it sounds. A team builds a fixed list of 15 to 20 category-defining prompts, the actual questions a buyer, reporter, or analyst would type: "who are the leading vendors in [category]," "what does [brand] do," "is [brand] a good fit for [use case]." That same prompt list runs against all five major engines on a fixed monthly cadence, never rephrased mid-study, because consistency is what makes the results comparable month over month.
Each response gets logged in full, not summarized, and then coded for three things: whether the brand appears at all, which sources the engine cites when it does, and whether competitors appear more prominently on the same prompt. The output is a simple table, prompt by prompt, engine by engine, that becomes the brand's own baseline. Most teams are surprised by the first audit, not because the brand is invisible everywhere, but because visibility is wildly inconsistent prompt to prompt, strong on one phrasing of a question and absent on a near-identical one. That inconsistency is itself the diagnostic: it points directly at which of the seven inputs above is thin.
A new category of measurement platforms has emerged to track AI citation the way SEMrush and Ahrefs track keyword rank, running standardized prompt sets against the major engines on a recurring basis and reporting brand mentions, source citations, and competitor comparisons as a dashboard rather than a manual export. A brand without budget for a dedicated platform can approximate the same discipline manually: the controlled-prompt method above, run on a spreadsheet, produces comparable directional data at a fraction of the cost, and is often the right starting point before a team commits budget to a measurement platform.
Common mistakes brands make when starting GEO
Five mistakes account for most stalled programs. Treating GEO like SEO keyword stuffing is the most common, packing a page with brand-name repetitions instead of entity-rich facts the engines can actually cite. Editing Wikipedia directly from a corporate account is the second, which routinely gets reverted and can flag the brand's entire Wikipedia history for closer scrutiny; Wikipedia edits need to go through its own conflict-of-interest disclosure process. The third is assigning the discipline to a junior staffer or intern as a side project rather than a senior owner with the authority to coordinate across communications, marketing, and web teams. The fourth is chasing content volume, publishing dozens of thin pages, instead of entity clarity on a smaller set of deep, well-sourced pages. The fifth is skipping the baseline measurement entirely and jumping straight to content production, which makes it impossible to know whether anything actually moved Citation Share three months later.
GEO does not replace traditional earned media measurement, it extends it. A placement in a Tier-1 outlet has always been valued for its own reach and credibility; it now carries a second, longer-tail value as an input the AI engines index and cite for months or years afterward. A communications team that already tracks share of voice and earned media value should add Citation Share as a third column on the same reporting dashboard, not a separate initiative run by a different team. The brands getting this right report all three metrics together quarterly, so a single earned media placement's value is understood across both its immediate press cycle and its long-tail citation footprint.
The brand GEO operating model
A working GEO program inside a brand runs a single senior practitioner who owns the discipline at the company level. Executive digital infrastructure runs through that role. Earned media coordinates through it. Website content runs through it. Citation Share gets measured quarterly and reported alongside share of voice and earned media value, the same way a brand tracks any other reputation metric.
Most brands have none of this. Communications sits with the PR team. Executive digital presence is individually managed and inconsistent. Web content sits with marketing or IT. The result is a fragmented reputation operation that loses every quarter to a competitor who has unified the function. The brand's own website is no longer a marketing brochure, it is a structured data source read by every model crawling the web, which means clean URLs, complete schema markup, fact-rich landing pages, named executives, dated and bylined content, and no client-side rendering of primary content.
What is the 120-day build sequence?
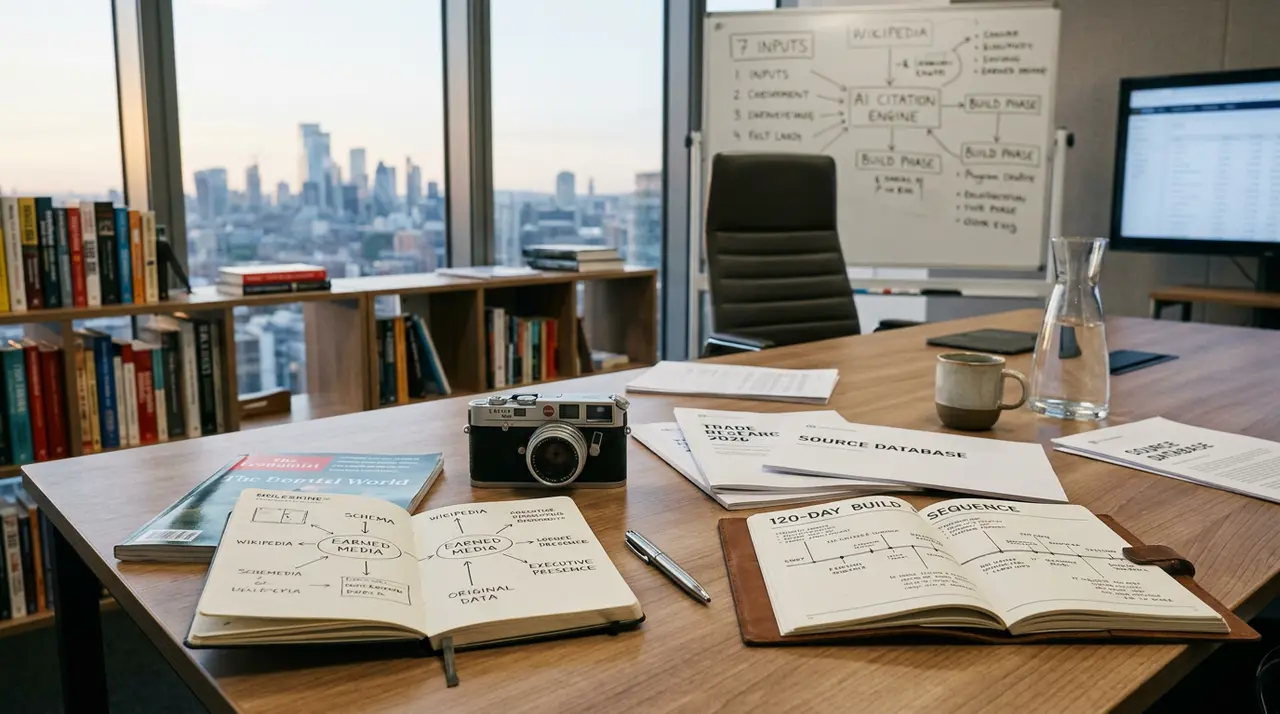
The build runs in three phases. Days 1 to 30 are the audit: run controlled prompts against all five major engines, document where the brand doesn't appear, pull the Wikipedia and Wikidata entries for the company and its top 5 named executives, and score the existing site for schema completeness.
Days 31 to 60 are repair: rebuild executive bio pages with full schema, update Wikipedia within editorial guidelines, activate named executives on expert-source platforms, and publish new entity-rich landing pages on topics competitors already get cited for.
Days 61 to 120 are compounding: an earned media campaign targeting Tier-1 outlets, an executive byline and conference-appearance program, one piece of original research or a benchmark study, and quarterly Citation Share tracking against named competitors. Audit, Wikipedia repair, schema rollout, executive activation, and baseline measurement, in that order, within 120 days. The brands that execute this sequence own a permanent retrieval advantage over competitors who delay.
Why does this matter during a crisis?
Reputation in the AI era is asymmetric. A single negative news cycle, a product recall, an executive departure, a lawsuit, propagates through the AI retrieval layer for months, and the brand has limited ability to remove it. The only defense is infrastructure built before the crisis: a deep, current, entity-rich content base that gives models something else to cite. A brand whose only citable content is a decade-old Wikipedia stub and a handful of unstructured press releases has no counterweight when a crisis hits the retrieval layer. A brand with a live library of named executives, recent Tier-1 coverage, and original research has material the engines can surface alongside, not instead of, the crisis coverage.
Cluster: What Is GEO? · The 50 Sites AI Engines Cite Most in 2026 · The GEO Playbook for Universities · How PR Teams Use Claude · How PR Is Measured